OneFixer: High-Quality and Consistent One-Step Autoregressive 3DGS Refinement for Driving Scenes
All videos use one-step denoising with autoregressive generation over 8-frame chunks.

Motivation
One-step causal refinement compounds errors. In autoregressive video diffusion, each prediction becomes the causal context for the next chunk. Reducing the denoising budget degrades each prediction, and because that prediction is reused as history, errors compound: the context drifts away from the ground-truth histories seen during training. This is visible in OmniDreams: moving from four denoising steps to one lowers latency but worsens both video fidelity and temporal consistency, even though every step is anchored by a 3DGS rendering.
Existing one-step stabilization pipelines can require complex training procedures. Self-forcing and distribution-matching objectives can improve autoregressive stability, as demonstrated by ArtiFixer, but preserving perceptual quality at a single denoising step remains challenging. Representative approaches additionally rely on multiple training stages, separate bidirectional and causal models, or auxiliary distillation and regularization objectives.
300-frame autoregressive rollout for 3DGS refinement. @N denotes the number of denoising steps.
OneFixer at a Glance
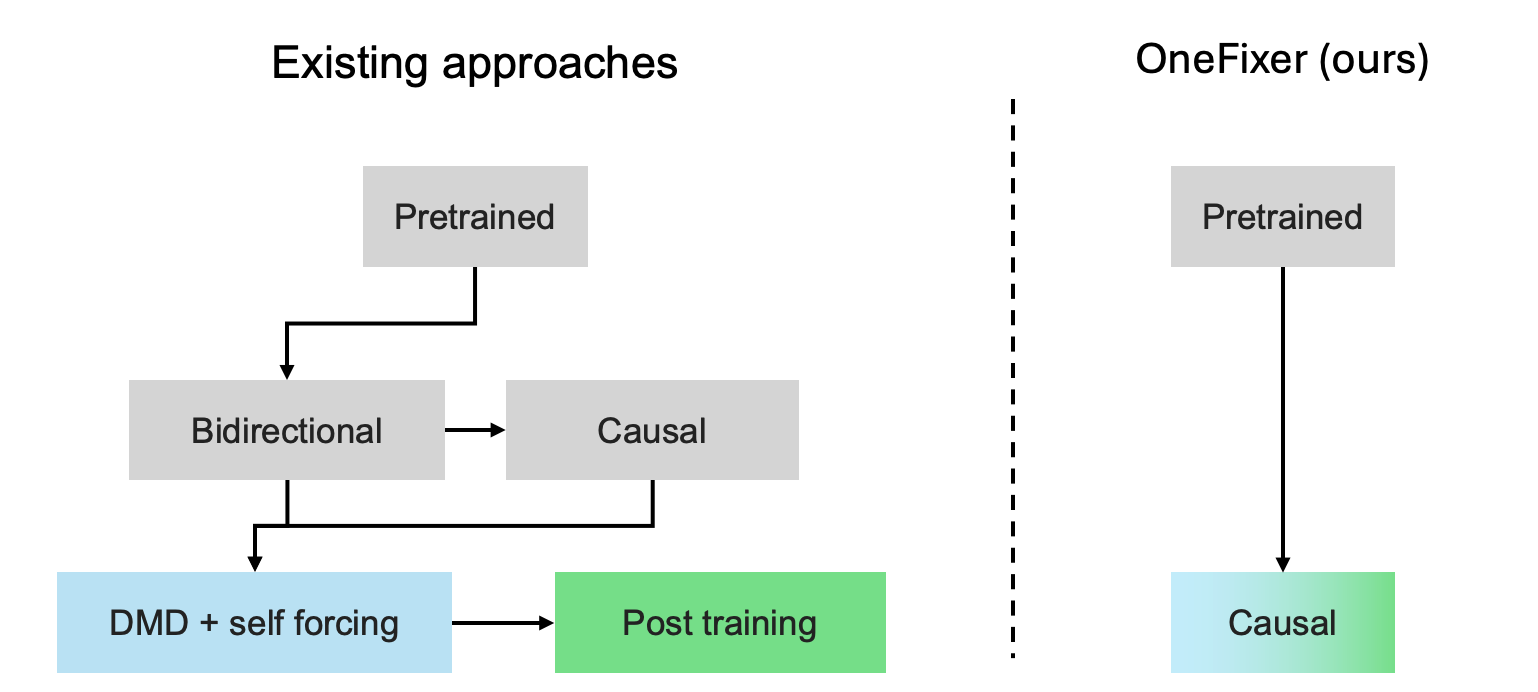
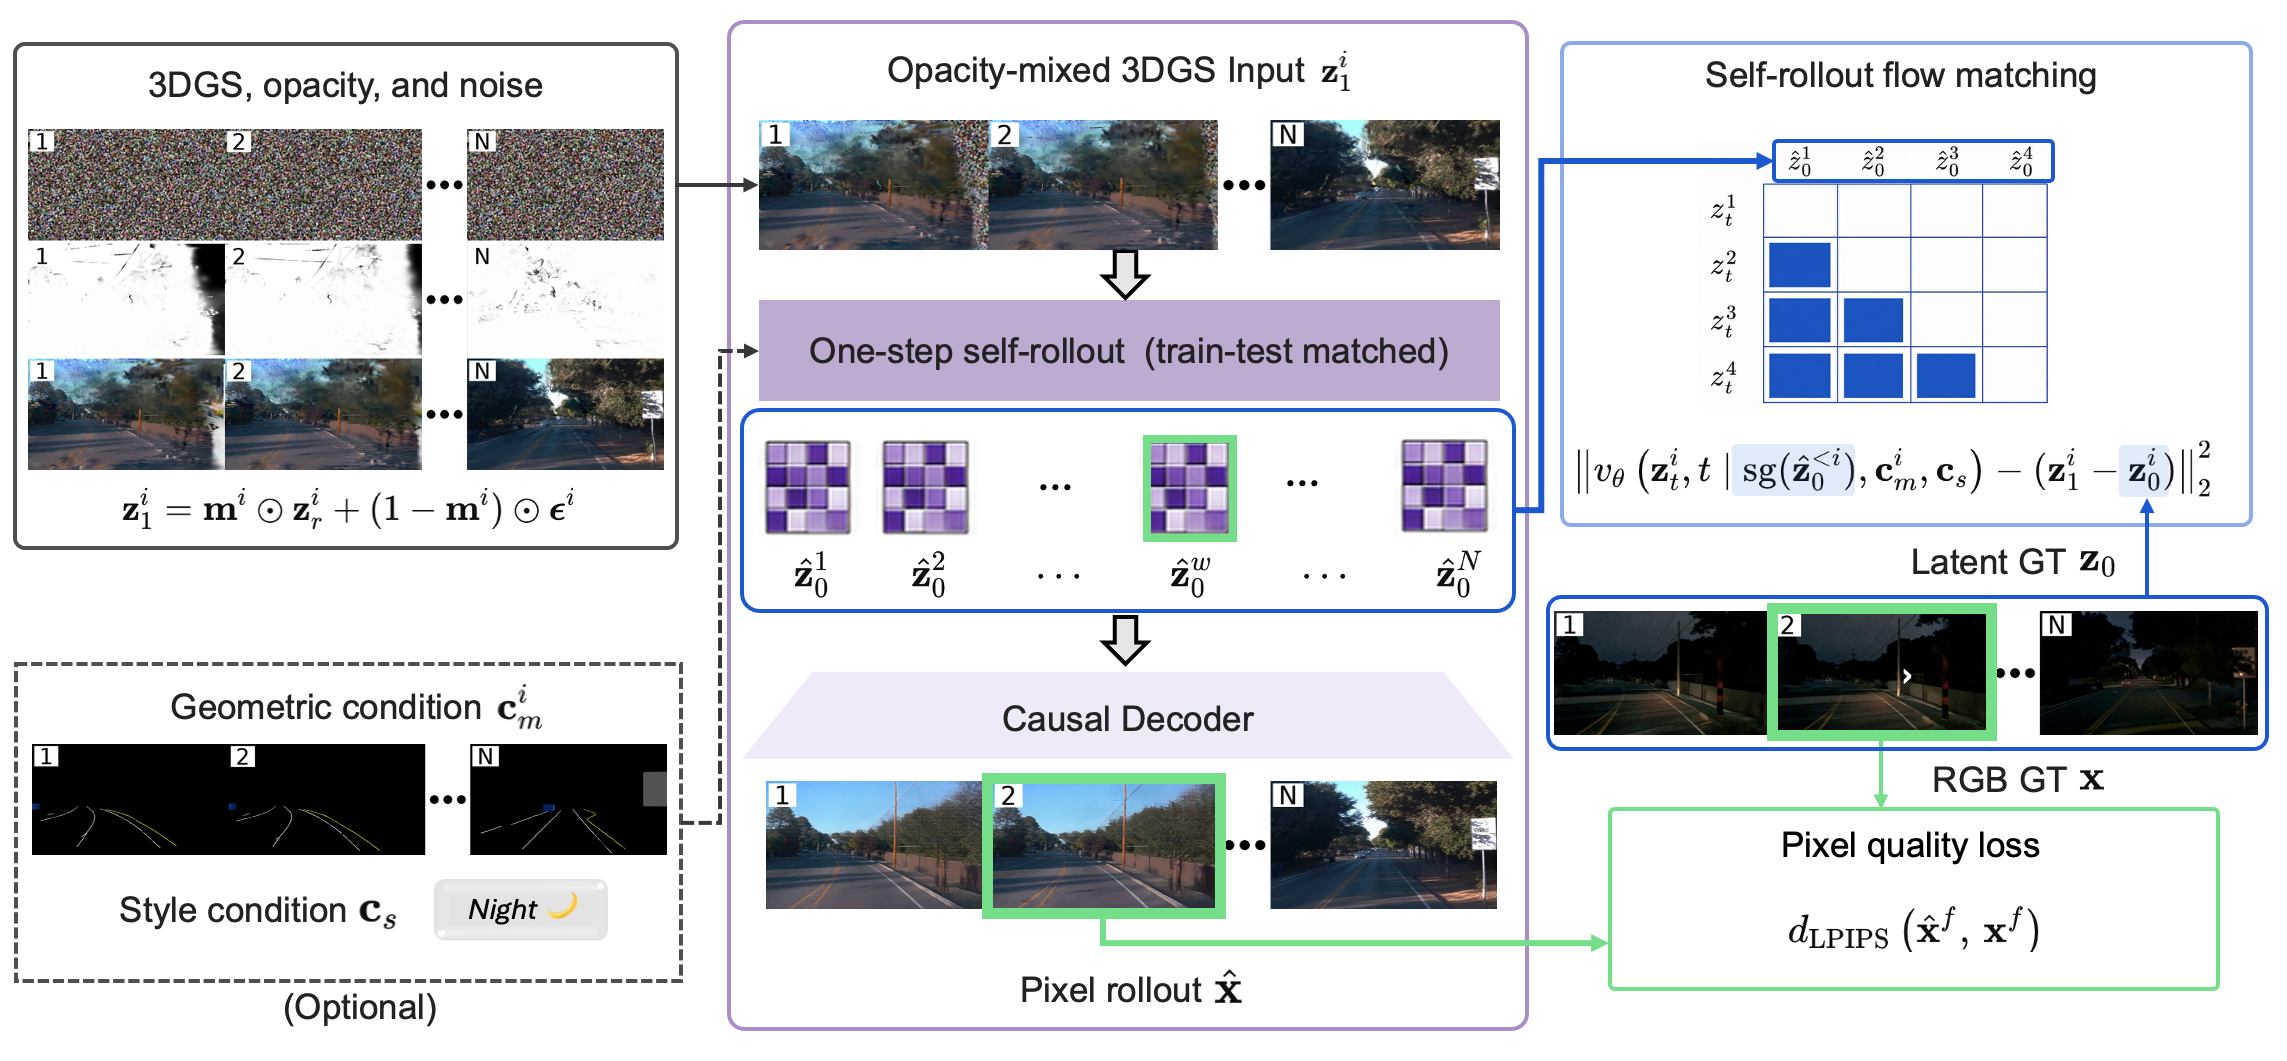
Comparison - Waymo (198 frames)
All methods are fine-tuned on the corresponding training split. † Uses the OmniDreams backbone, same as OneFixer.
Comparison - Internal (900 frames)
All methods are fine-tuned on the corresponding training split. † Uses the OmniDreams backbone, same as OneFixer.
Comparison - Novel View (300 frames)
All methods are fine-tuned on the corresponding training split.
Additional Results
Closed Loop Simulation
The black dashed line indicates the logged trajectory; outside this path, no 3DGS reconstruction is available.
Stylization
Multi-Camera Generation
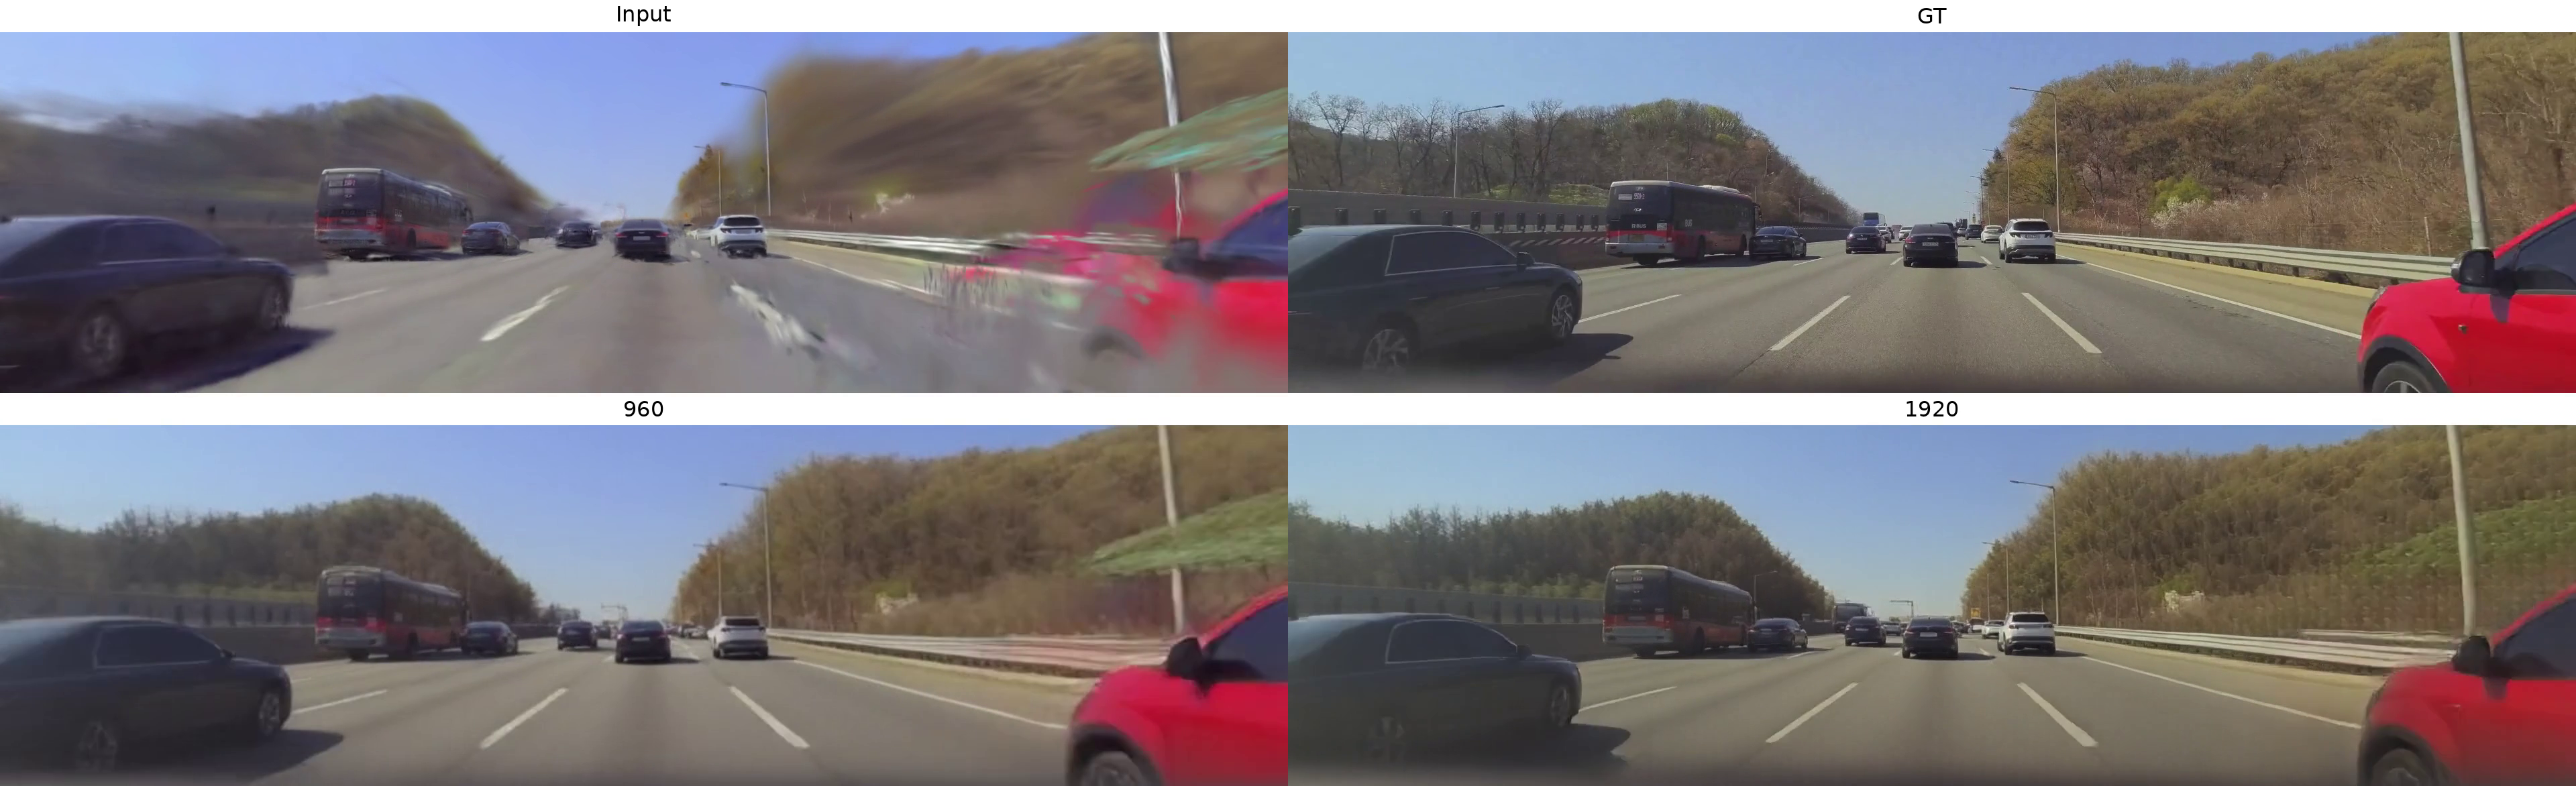
High Resolution
Non-driving Scenes
All methods are fine-tuned on the corresponding training split. OneFixer is initialized from OmniDreams, a driving-scene generation video model.